The inference pipeline, made ready to ship.
Context photographs, a 3D proxy and a few camera keyframes go in; a collision-free camera path, the right context photos per chunk, a written prompt and the generated video come out. This page shows what changed in speed and what it costs in fidelity, measured against real photographs and against the published videos.
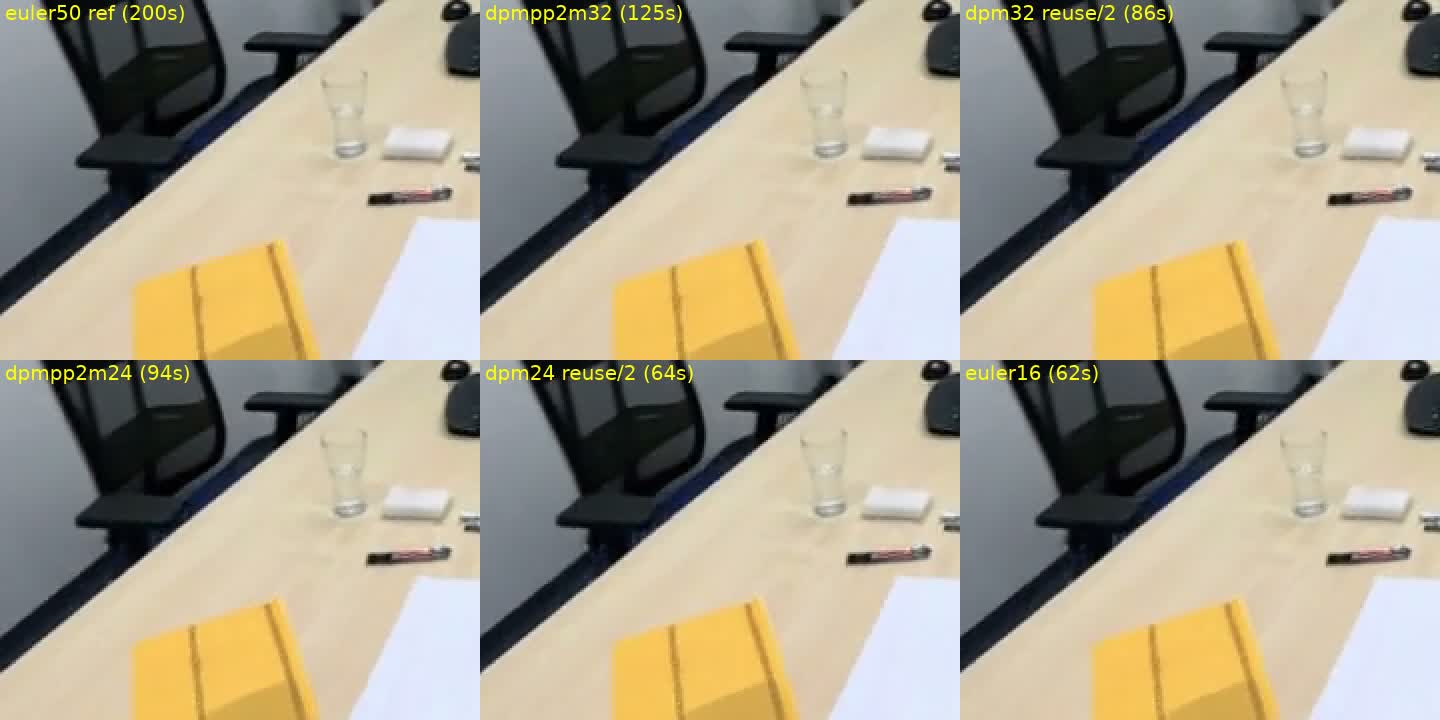
Sampling: the same chunk under every setting
One 124-frame chunk of the office case, eight A800 GPUs in tensor parallel, compared with the 50-step Euler sampling the page videos were made with. The latent error is the relative distance of the final latent from the reference; sharpness is the gradient energy of the frames relative to the reference (below 1 = softer).
| Setting | s / chunk | latent error | PSNR | sharpness |
|---|---|---|---|---|
| Euler · 50 steps (reference) | 195 | 0.000 | 138.1 | 1.000 |
| Euler · 32 | 125 | 0.026 | 38.3 | 0.957 |
| DPM++ 2M · 32 | 125 | 0.024 | 38.6 | 0.981 |
| DPM++ 2M · 24 | 94 | 0.037 | 36.4 | 0.962 |
| DPM++ 2M · 32 · reference tokens reused on every second step | 86 | 0.035 | 37.0 | 0.974 |
| DPM++ 2M · 24 · reused | 64 | 0.049 | 33.5 | 0.951 |
| Euler · 16 | 62 | 0.058 | 34.5 | 0.924 |
Held-out photographs: which context photos, which prompt
A camera path is laid through a few consecutive real photo poses; those photos and their neighbours are removed from the pool, so the frames at those poses can be compared with the real photographs (50-step sampling, same seed everywhere). Metrics are averaged over the key frames inside the photographed area.
| Variant | PSNR | SSIM | LPIPS | cases |
|---|---|---|---|---|
| new selection · captioned prompt | 14.43 | 0.437 | 0.409 | 10 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 14.51 | 0.437 | 0.407 | 10 |
auditorium a
5 held-out photo poses on the path, 121 of 128 photos left in the pool. Frame 62:
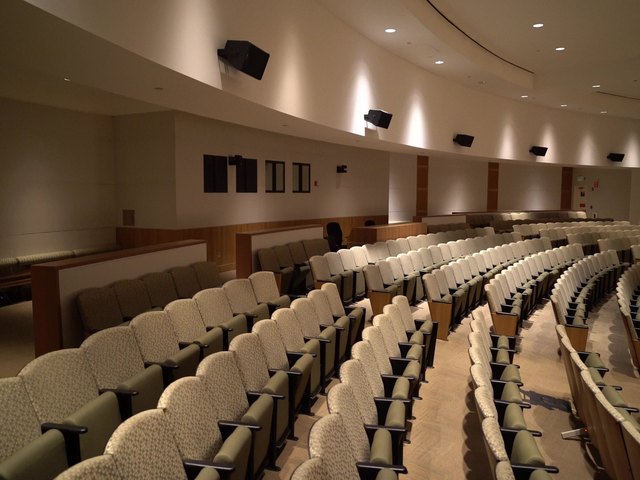
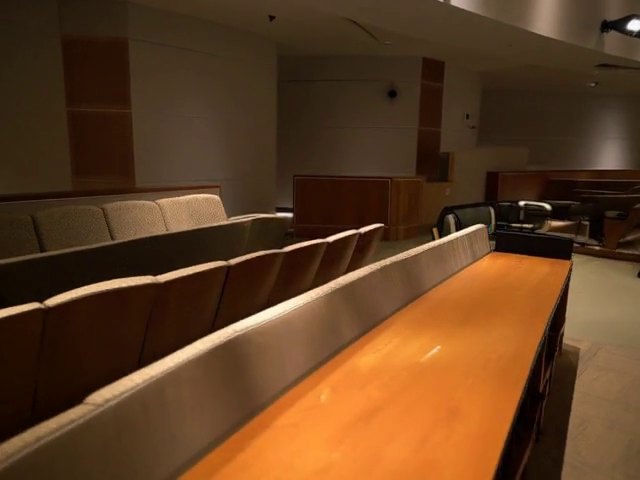
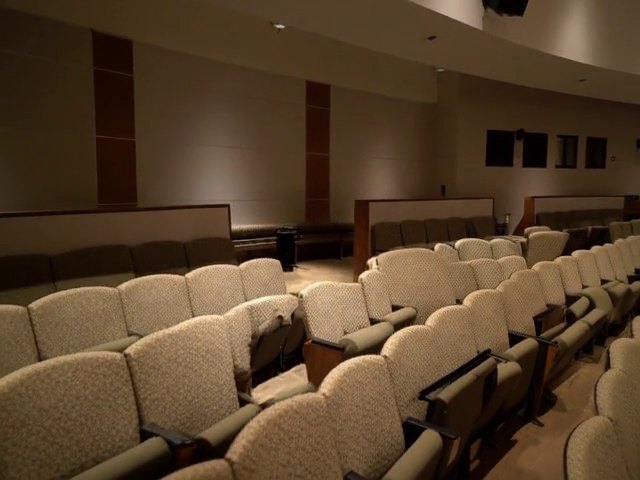
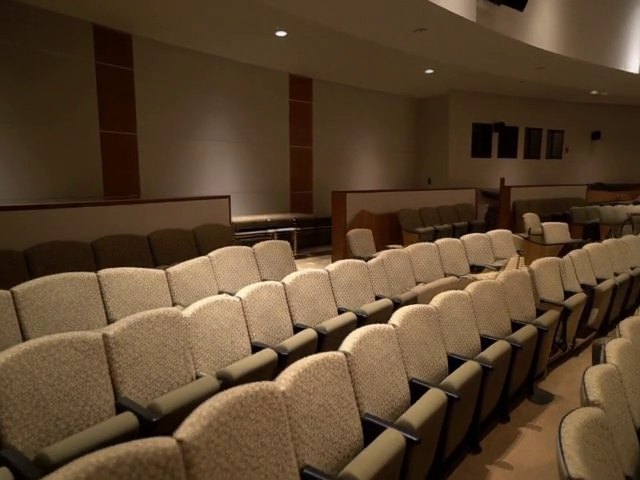
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 12.68 | 0.336 | 0.636 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 12.75 | 0.336 | 0.637 |
bedroom a
8 held-out photo poses on the path, 277 of 300 photos left in the pool. Frame 70:
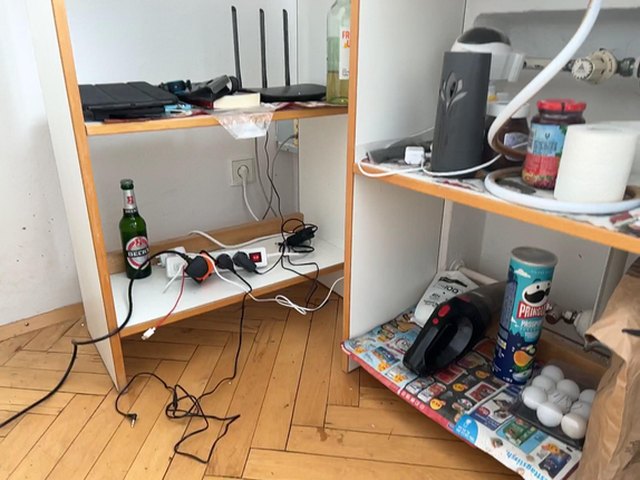
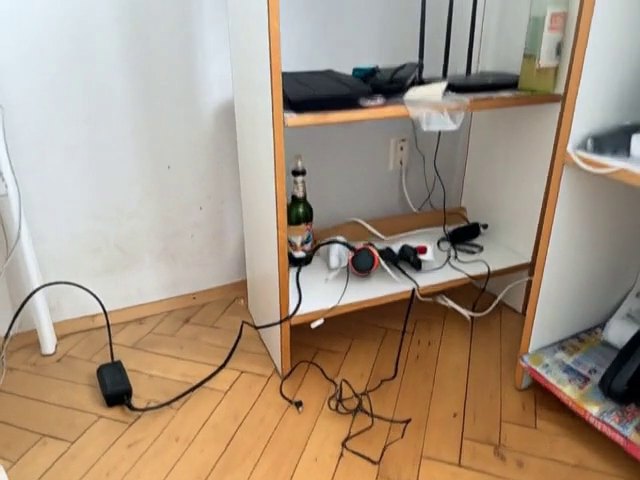
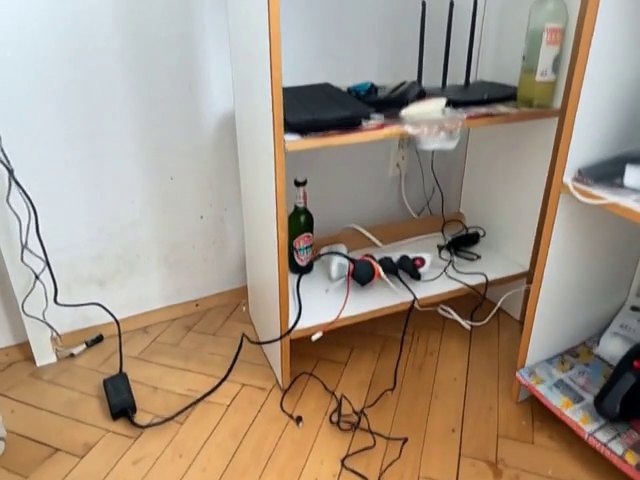
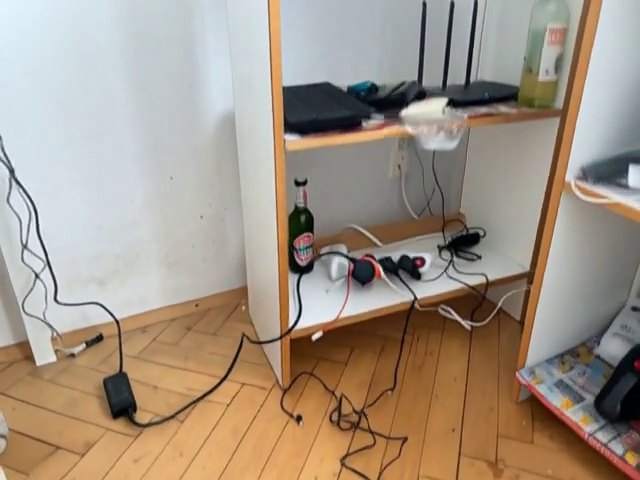
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 11.96 | 0.400 | 0.634 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 11.96 | 0.399 | 0.633 |
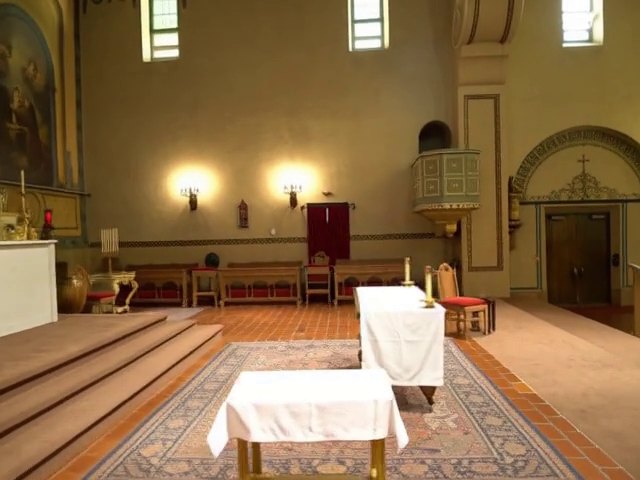
church a
5 held-out photo poses on the path, 121 of 128 photos left in the pool. Frame 62:
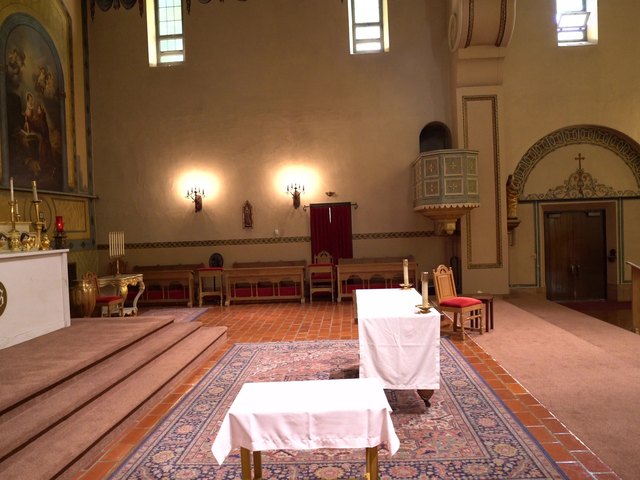
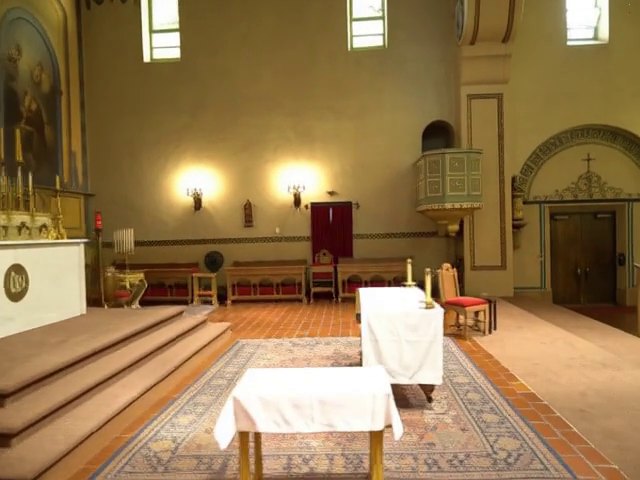
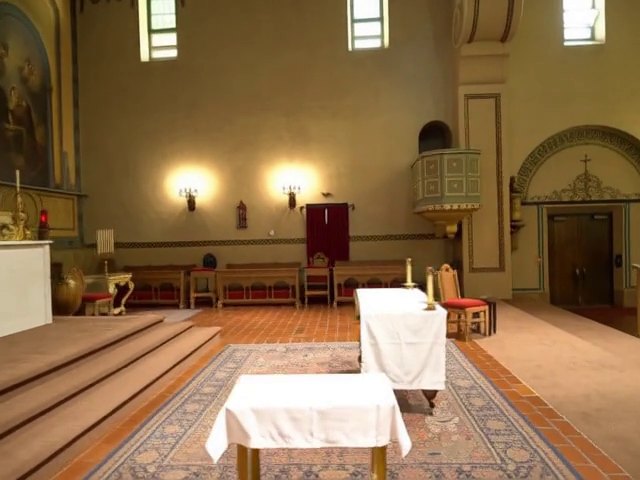
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 16.21 | 0.404 | 0.294 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 16.23 | 0.400 | 0.291 |
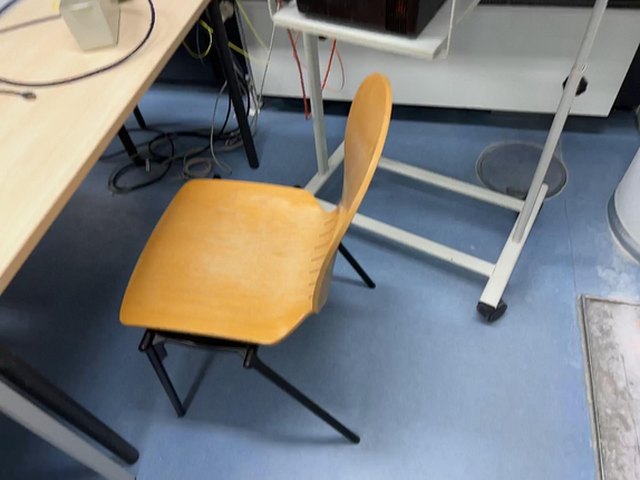
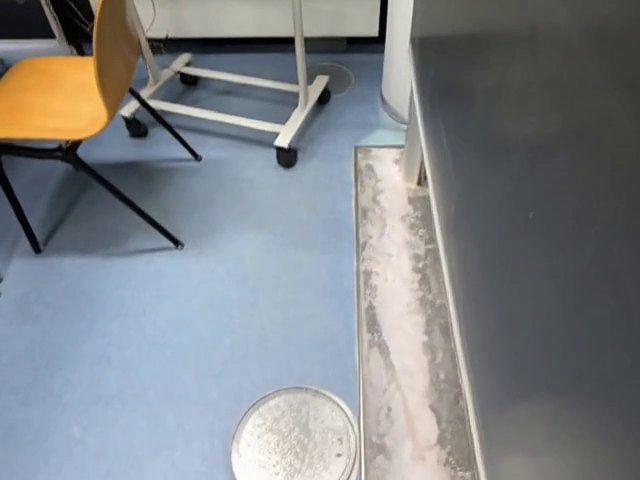
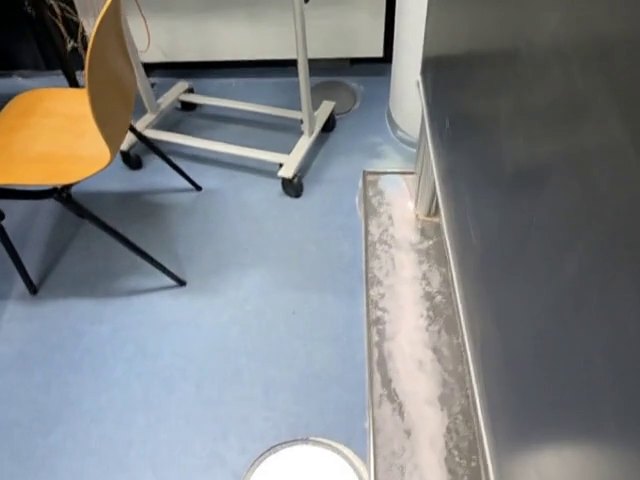
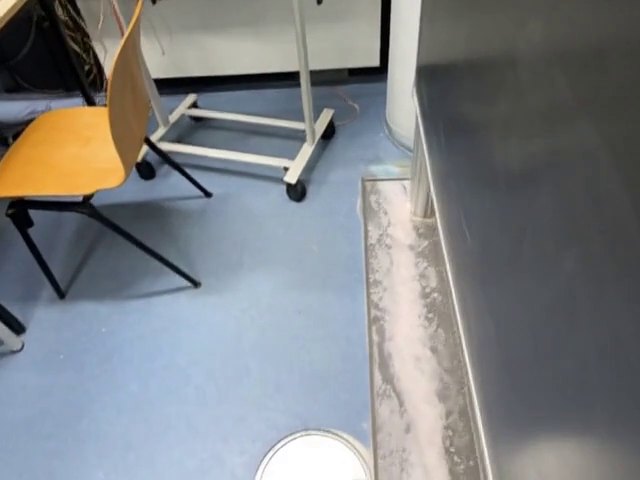
classroom a
6 held-out photo poses on the path, 288 of 300 photos left in the pool. Frame 74:
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 8.45 | 0.398 | 0.755 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 8.49 | 0.399 | 0.753 |
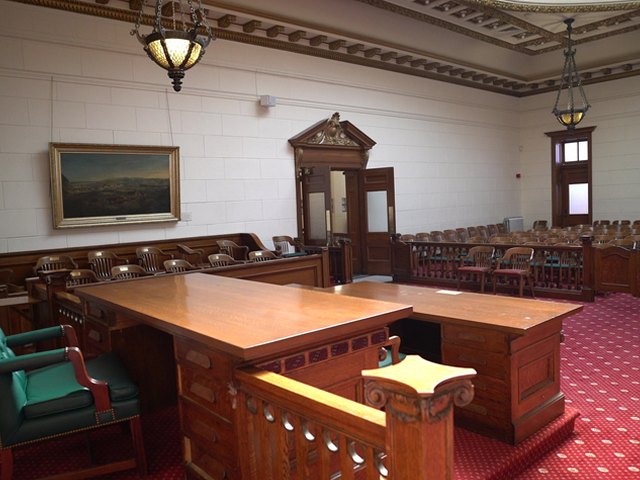
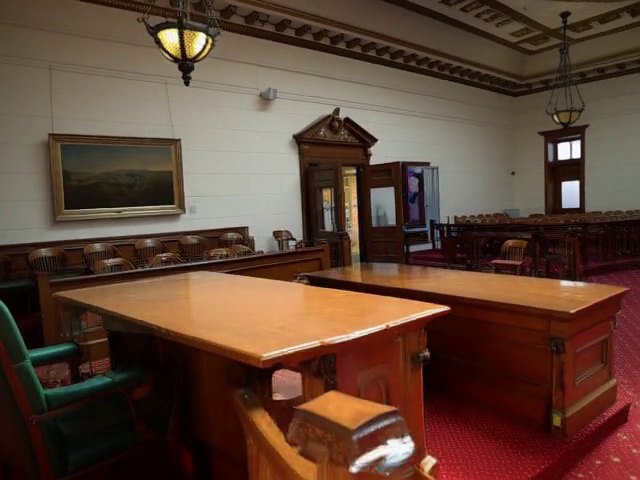
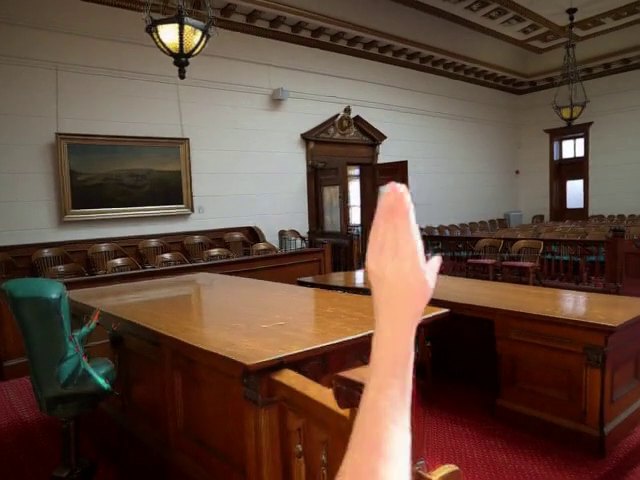
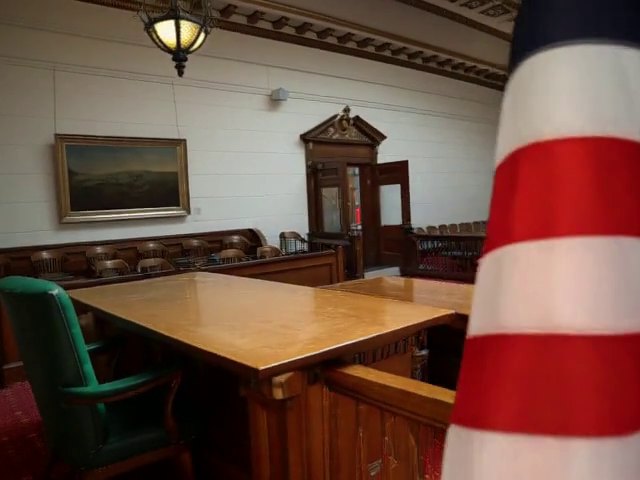
courtroom a
5 held-out photo poses on the path, 57 of 64 photos left in the pool. Frame 62:
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 12.77 | 0.302 | 0.480 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 12.72 | 0.298 | 0.484 |
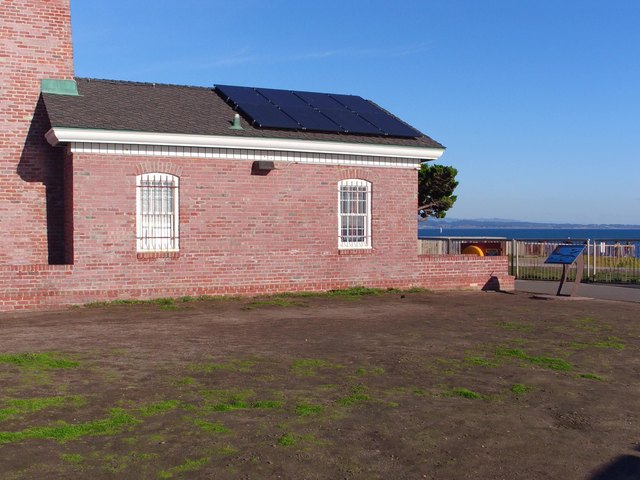
lighthouse a
5 held-out photo poses on the path, 121 of 128 photos left in the pool. Frame 62:
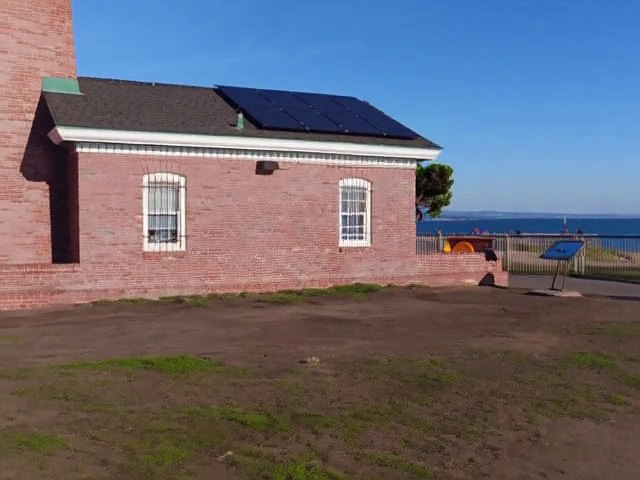
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 19.00 | 0.570 | 0.205 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 19.06 | 0.571 | 0.205 |
msm a
5 held-out photo poses on the path, 55 of 96 photos left in the pool. Frame 62:
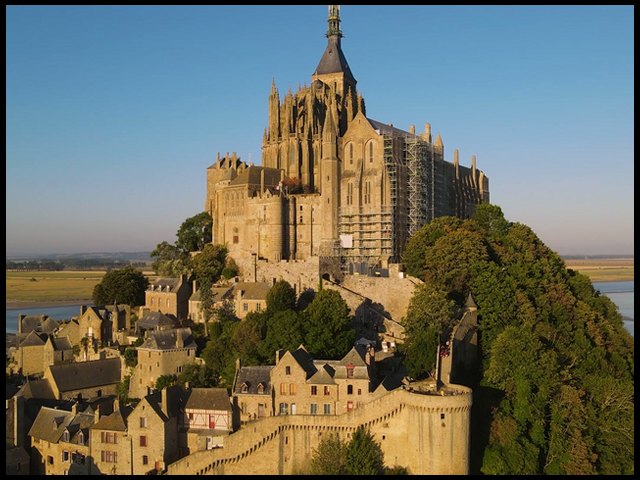
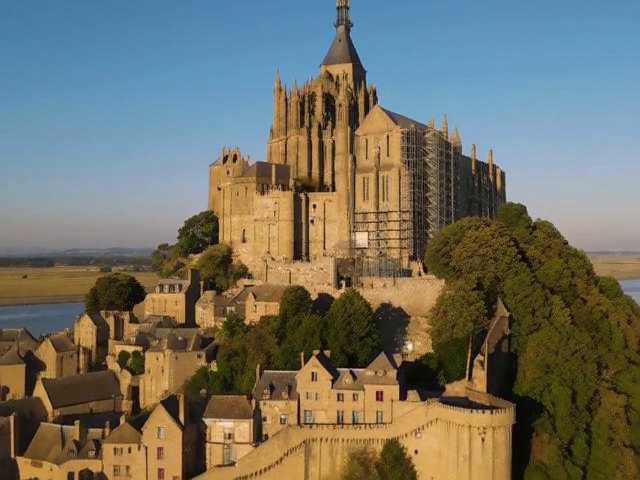
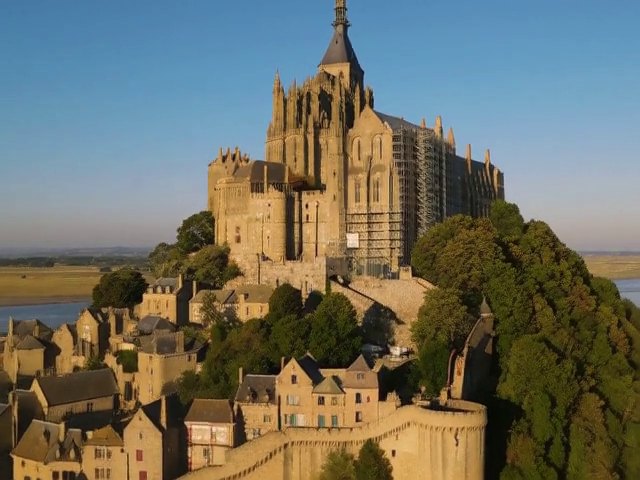
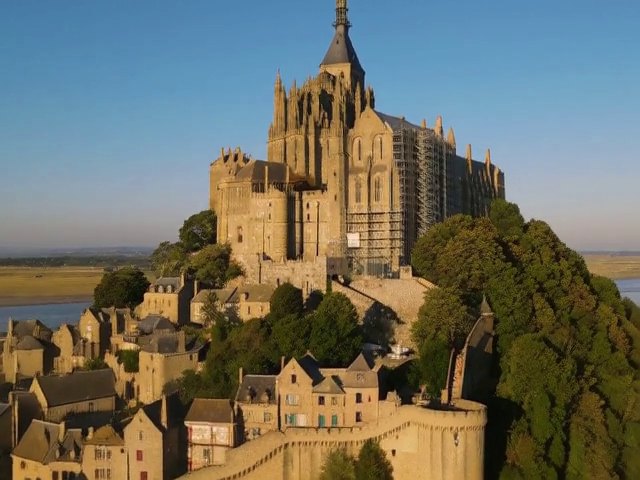
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 17.48 | 0.470 | 0.248 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 17.45 | 0.468 | 0.250 |
museum a
5 held-out photo poses on the path, 121 of 128 photos left in the pool. Frame 62:
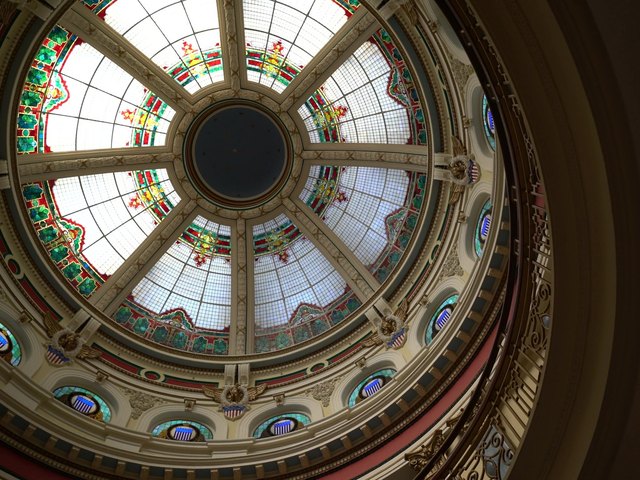
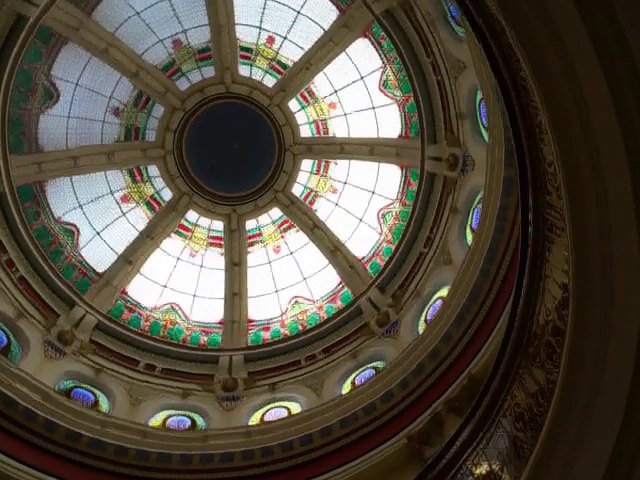
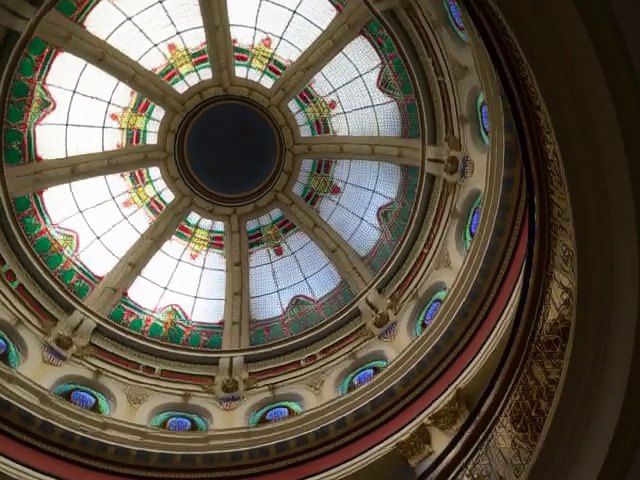
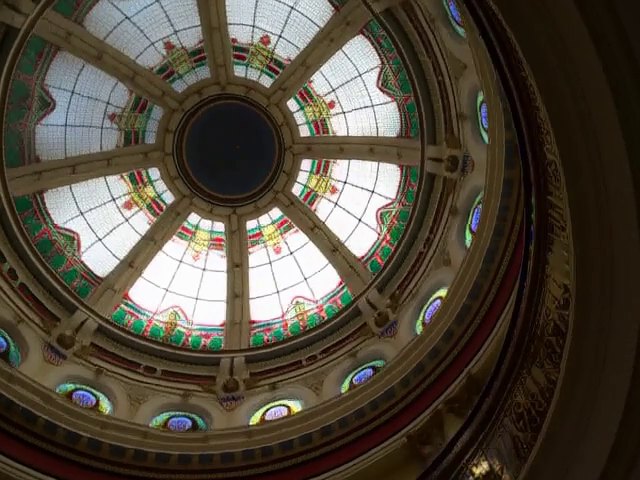
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 12.86 | 0.191 | 0.317 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 13.43 | 0.191 | 0.306 |
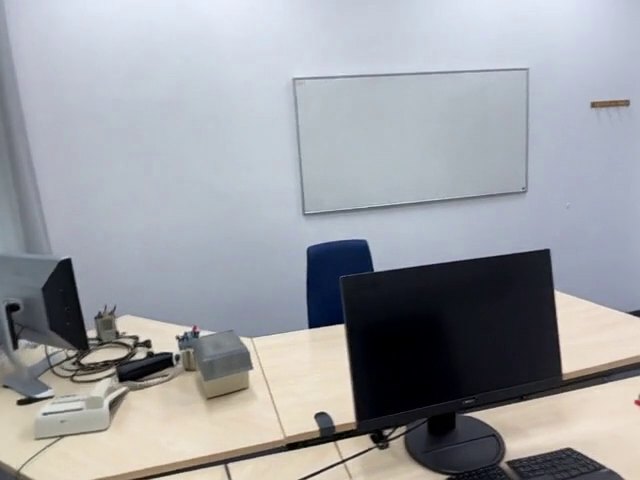
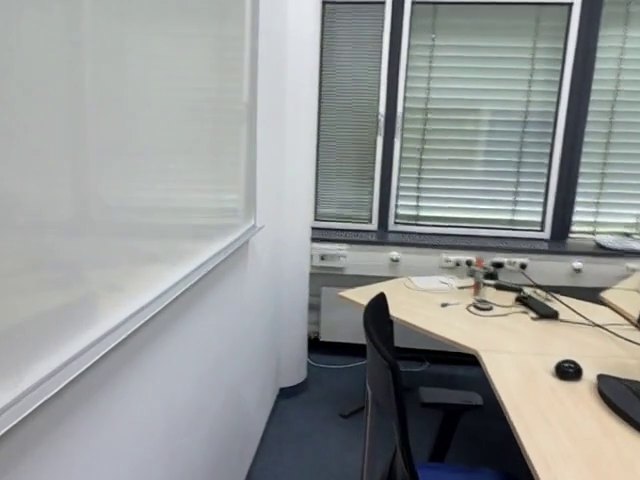
office a
8 held-out photo poses on the path, 286 of 300 photos left in the pool. Frame 70:
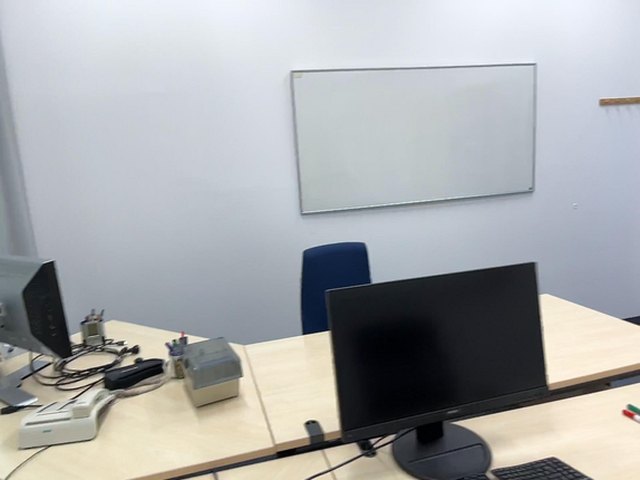
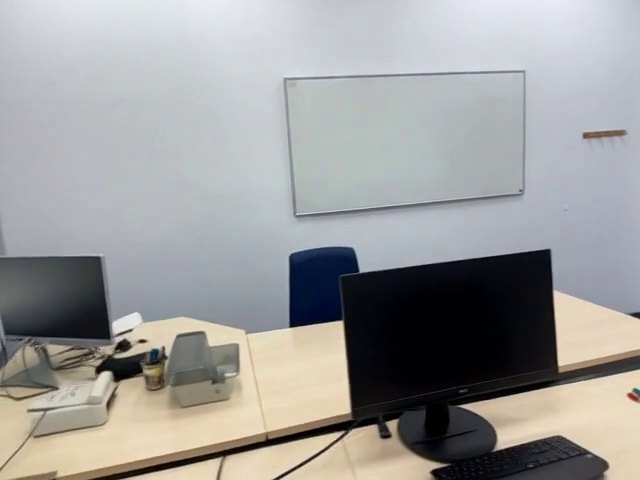
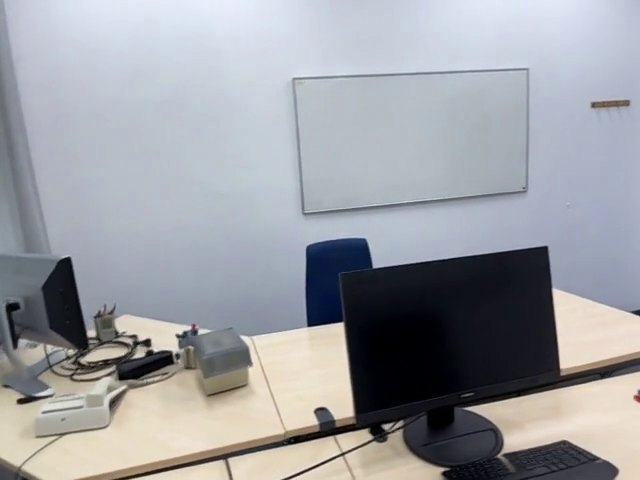
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 16.50 | 0.675 | 0.241 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 16.46 | 0.673 | 0.240 |
office b
8 held-out photo poses on the path, 280 of 300 photos left in the pool. Frame 70:
| Variant | PSNR | SSIM | LPIPS |
|---|---|---|---|
| new selection · captioned prompt | 16.38 | 0.627 | 0.285 |
| new selection · captioned · averaged checkpoints 1400/1500/1600 | 16.55 | 0.634 | 0.274 |
Project-page cases, re-rendered
| Case | sharpness new / published | artifact score new / published | largest seam jump new / published | new vs published PSNR / SSIM / LPIPS |
|---|---|---|---|---|
| Alameda house | 0.99 | 1 / 0 | 2.2 / 1.8 | 20.7 / 0.72 / 0.14 |
| Bedroom | 1.08 | 0 / 0 | 2.5 / 2.2 | 18.8 / 0.70 / 0.18 |
| Mission church | 1.28 | 3 / 3 | 1.4 / 1.4 | 16.3 / 0.40 / 0.33 |
| Mont-Saint-Michel | 1.28 | 0 / 0 | 1.9 / 1.9 | 18.4 / 0.64 / 0.27 |
| Rotunda museum | 1.14 | 1 / 1 | 3.2 / 2.8 | 16.0 / 0.39 / 0.26 |
| Office | 0.95 | 0 / 0 | 1.7 / 1.7 | 16.5 / 0.68 / 0.22 |
Sharpness is the gradient energy of the new video over the published one. The artifact score is the sum over chunks of a vision-language judge's 0–3 rating of four frames per chunk, run identically on both videos. The seam jump is the frame change at a chunk boundary relative to the typical change, both normalised by the proxy video's own motion. The last column compares the two renderings with each other (different seeds, contexts and prompts), so it measures how close they are, not which is right.
Office
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 360 s of sampling for 3 chunks.
Bedroom
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 362 s of sampling for 3 chunks.
Alameda house
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 590 s of sampling for 4 chunks.
Rotunda museum
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 482 s of sampling for 4 chunks.
Mission church
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 470 s of sampling for 4 chunks.
Mont-Saint-Michel
Left: the published video (50-step Euler, hand-picked contexts, Codex-written prompt). Right: the new pipeline on the same camera path (32 steps dpmpp2m, automatic contexts and captions): 437 s of sampling for 4 chunks.
End to end
The office case above (three chunks, 304 frames, a path planned from six keyframes) timed on one eight-GPU node, from the request to the finished video.
| Mode | seconds | What the time goes to |
|---|---|---|
| Published pipeline (reference) | 877 | 50-step Euler; loading the model the original way (175 s), encoding conditions in a separate process, 200 s per chunk; another 568 s the first time a node copies the weights |
| Cold start | 650 | nothing resident: 82 s to load the prompt and encoding models, 73 s of preparation (path 2, contexts 8, proxy 13, prompts 16, files 5, conditions 31), 26 s to load the video model, 357 s of sampling at 32 steps DPM++ 2M, 45 s of chunk hand-over and decoding |
| Resident services | 481 | prompt/encoding service and the eight-GPU sampler stay loaded: 45 s until the first chunk is handed to the sampler (path 2, contexts 10, proxy 13, prompts 11-16, files 6), then sampling of chunk 0 overlaps the encoding of chunks 1 and 2; 432 s of sampling and hand-over |
| Cold start, --fast | 559 | as the cold start, with the reference tokens reused on every second sampling step and the text tokens frozen: 248 s of sampling (80/84/84 s per chunk) instead of 357 s |
Notes
- Model: the same v3-mix step-1500 LoRA on MiniMax-H3 as the project page; 640×480, 24 fps, chunks of 124 frames with 34 overlapping.
- Loading: the LoRA is merged once and the weights stored per GPU, so the eight-GPU model loads in about 12 s instead of 175 s and needs 13 GB per GPU instead of 39 GB; the outputs match the original loader within numerical noise.
- Context photos are chosen per chunk by a per-pixel score (visibility in the proxy, resolution and viewing angle relative to the target camera, sharpness), keeping a second view of every surface where one exists.
- Prompts are written by a local Qwen3-VL-8B from the photos and the planned camera moves; the camera moves themselves are computed from the path.